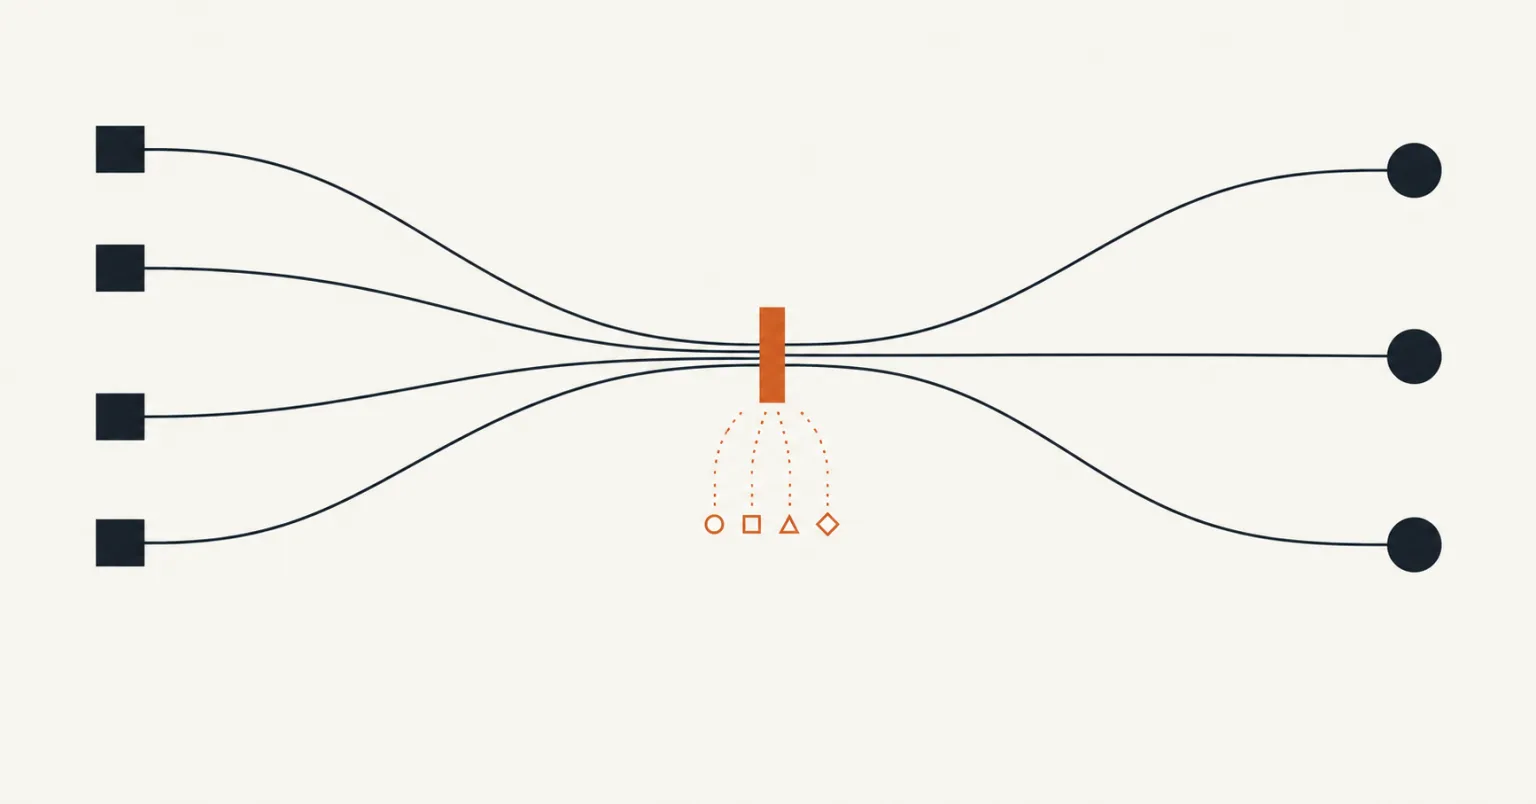
Your AI gateway should make the work observable
A practitioner’s case for running an LLM proxy raises an operational question: can your team explain which application called which model, under whose credentials, and with what result?
As a leader: Require a traceable identity and an accountable operator for each application using a shared AI gateway.
As an individual: Trace one real request from the client through the gateway to the provider before relying on aggregate usage charts.
Read the analysis →