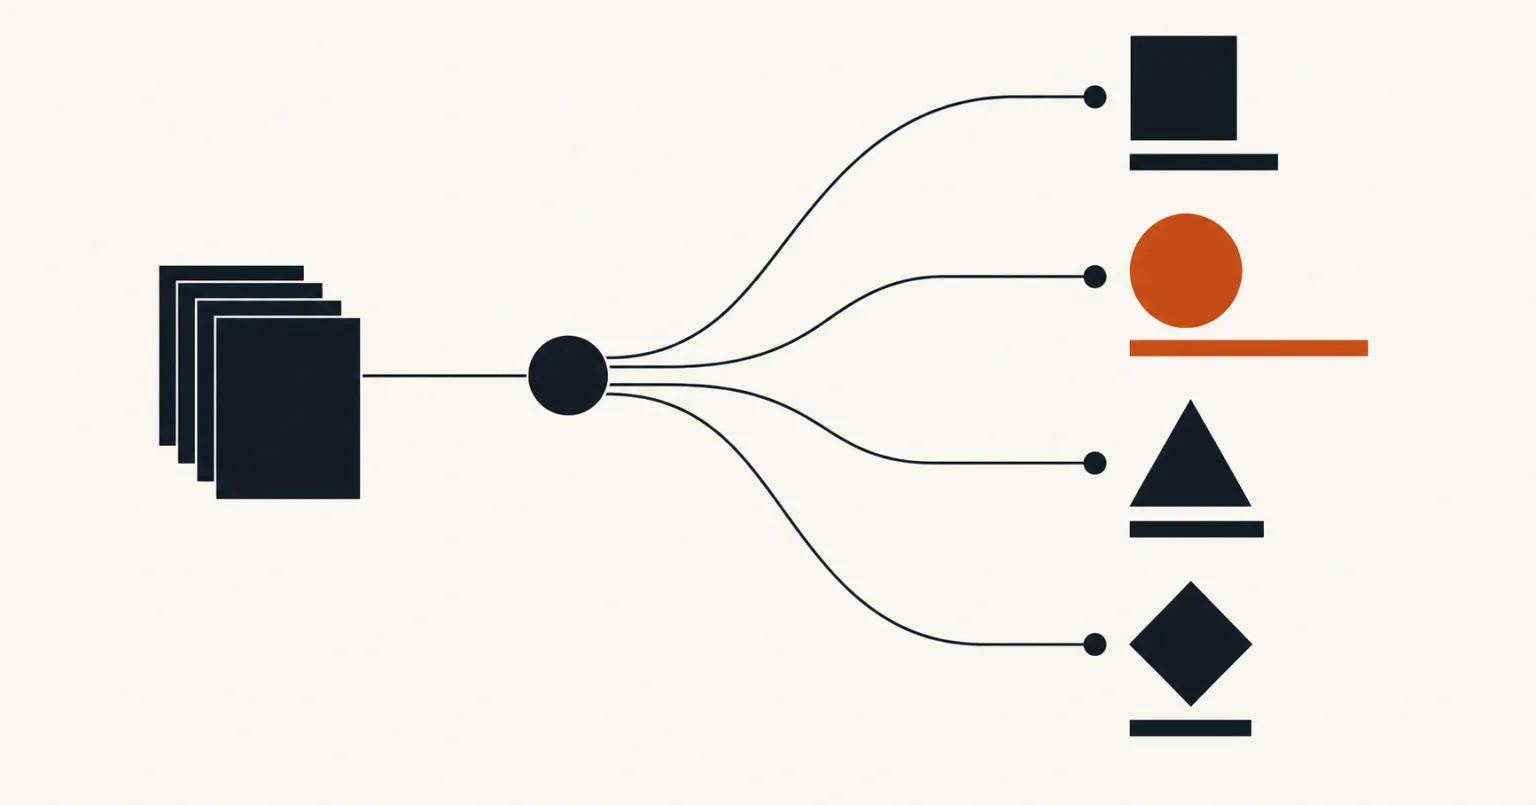
Sometimes the next step needs an explanation, a draft, or a plan. Sometimes it needs a selection from a set of defined options. If the answer has to fit that small interface, why ask for a paragraph and then build another component to interpret it? That question puts the shape of the answer beside the choice of model.
A preprint on typed decisions examines fixed-option outputs derived in one forward pass. The authors describe an internal coding-session triage use and experiments with adapted open models. They report substantial cost differences in their setting while also exposing limitations in small public benchmarks and sensitivity to the training corpus. Those details matter: an inexpensive internal configuration is evidence for a local experiment, not a universal cost or accuracy guarantee.
Look for a repeated decision where the receiving system already knows the possible answers. The opportunity begins with that existing contract. If the labels are understood and the boundary is clear, the team can ask whether a simpler interface would deliver the decision with less surrounding work.
Start with a stable question
Put the labels in front of the people who will review the results. Can they apply each label consistently? Where do options overlap, and what happens when none fits? Settle those questions before optimizing the selection step. A faster output still carries the ambiguity of the labeling task into the system that receives it.
Choose examples with reviewed outcomes and preserve the reasoning behind disputed labels. Include the cases that people find difficult, not just the clean examples used to introduce the task. A narrow interface needs a clear policy for ambiguity because it gives the model fewer ways to explain an uncertain situation.
Also check whether the option set is genuinely stable. A classifier built around a changing business taxonomy needs a maintained process for adding, merging, and retiring labels. The release record should connect each model and evaluation with the taxonomy it actually used.
Separate the decision from its explanation
A typed output can make an integration easier to validate. It can identify the selected option and expose scores without requiring another component to interpret a paragraph. That does not establish that the scores are calibrated or that the selected option is correct.
Decide what evidence a person needs when reviewing the result. The application may retain source references or separately request an explanation for a subset of cases. An explanation should remain connected to the actual decision process rather than being treated as independent proof that the decision was justified.
Use the output contract to make unsupported cases visible. If the evidence falls outside the task, the system needs a defined response such as deferral or a separate unsupported category. Forcing every input into a confident-looking option can hide a boundary problem behind tidy structured output.
Compare against modest baselines
A specialized language-model path should earn its place against simpler alternatives appropriate to the task. Keep the input evidence, labels, and test split constant. Compare the relevant error types, latency, usage, and operational complexity, not just whether a model has a more sophisticated name.
Preserve a held-out evaluation that was not used to develop the prompt, label rules, or model. The preprint is explicit about some results being developed with public benchmark items in view. That makes the evidence useful for understanding an approach while limiting the claim that the number establishes generalization.
Run the comparison across the groups of inputs that matter operationally. A configuration may be attractive for common cases and unsuitable for a specialized department’s terminology. The deployment choice can reflect that difference if the evaluation reports it clearly.
Make confidence support an action
Follow a confidence value to the action it is meant to support. Does the score help separate correct decisions from incorrect ones? Does a proposed threshold still help on held-out examples? A small probability distribution can be a convenient output, but the people setting the threshold still need evidence that the measurement helps them choose what to do next.
Define what happens to deferred cases and measure the resulting human workload. A lower model-serving cost may be attractive even with a conservative review path, provided the review queue remains supportable. Conversely, a cheap classifier that floods the queue with unclear cases may offer little practical improvement.
Revisit the threshold when the task, labels, or input distribution changes. Retain the version used to select it and the evidence behind that selection. This makes a later operating change a measured decision instead of a quiet adjustment to improve a dashboard.
Inspect errors by option as well as overall accuracy. A frequent class can dominate the score while a rare, consequential outcome remains poorly handled.
Pilot a repeated decision
Choose a fixed-option step that runs frequently and already has an accountable reviewer. Test the current workflow, a suitable simple baseline, and the proposed typed path on the same held-out records. Include the cost of handling errors and deferrals in the result.
Bring the interface back into the efficiency discussion. What does the next step need to receive, and what evidence does its operator need when the answer is uncertain? A well-defined selection can be a useful answer in its own right. Give that answer a clear meaning and a supported path for the cases it cannot settle. Then measure whether the simpler exchange helps the work.